Download Developing AI Apps and Agents on Azure.AI-103.PassLeader.2026-11-16.62q.vcex
| Vendor: | Microsoft |
| Exam Code: | AI-103 |
| Exam Name: | Developing AI Apps and Agents on Azure |
| Date: | Nov 16, 2026 |
| File Size: | 2 MB |
How to open VCEX files?
Files with VCEX extension can be opened by ProfExam Simulator.
Purchase
Coupon: TAURUSSIM_20OFF
Discount: 20%
Demo Questions
Question 1
You have a Microsoft Foundry project that contains a model deployment.
You have an application that calls the deployment by using the Azure OpenAI v1 API and DefaultAzureCredential.
The developers at your company receive HTTP 403 errors when they send inference requests, even after running az login.
You need to ensure that the developers can perform model inference. The solution must follow the principle of least privilege.
Which role-based access control (RBAC) role should you assign to the developers?
- Cognitive Services User
- Cognitive Services OpenAI User
- Contributor
- Cognitive Services Data Reader
Correct answer: B
Explanation:
To resolve the HTTP 403 Forbidden errors when making inference calls via the Azure OpenAI v1 API and DefaultAzureCredential, users must be assigned the Cognitive Services OpenAI User built-in Azure RBAC role. Why This Happens Running az login successfully authenticates the user with Microsoft Entra ID, but it does not grant data-plane access permissions. By default, standard control-plane roles (like Reader or Foundry User) only allow users to view project metadata or manage settings, not send prompts to the model deployment endpoint itself. Recommended Role Definition Role Name: Cognitive Services OpenAI User Permissions Granted: This role provides the absolute minimum privileges required to execute chat completions, embeddings, and general inference tasks (Microsoft.CognitiveServices/accounts/OpenAI/deployments/search/action and Microsoft.CognitiveServices/accounts/OpenAI/deployments/causalLanguageModeling/action). It does not allow users to deploy new models, view access keys, or alter configurations Scope Placement: Assign this role to the users (or a Microsoft Entra ID Group) at the Azure OpenAI resource level or the Resource Group level containing your Microsoft Foundry infrastructure. Reference: https://learn.microsoft.com/en-us/azure/foundry-classic/openai/how-to/managed-identity To resolve the HTTP 403 Forbidden errors when making inference calls via the Azure OpenAI v1 API and DefaultAzureCredential, users must be assigned the Cognitive Services OpenAI User built-in Azure RBAC role.
Why This Happens
Running az login successfully authenticates the user with Microsoft Entra ID, but it does not grant data-plane access permissions. By default, standard control-plane roles (like Reader or Foundry User) only allow users to view project metadata or manage settings, not send prompts to the model deployment endpoint itself.
Recommended Role Definition
Role Name: Cognitive Services OpenAI User
Permissions Granted: This role provides the absolute minimum privileges required to execute chat completions, embeddings, and general inference tasks
(Microsoft.CognitiveServices/accounts/OpenAI/deployments/search/action and Microsoft.CognitiveServices/accounts/OpenAI/deployments/causalLanguageModeling/action). It does not allow users to deploy new models, view access keys, or alter configurations
Scope Placement: Assign this role to the users (or a Microsoft Entra ID Group) at the Azure OpenAI resource level or the Resource Group level containing your Microsoft Foundry infrastructure.
Reference:
https://learn.microsoft.com/en-us/azure/foundry-classic/openai/how-to/managed-identity
Question 2
You have a Microsoft Foundry project that contains an agent. The agent has a Model Context Protocol (MCP) tool that queries a knowledge base stored in Azure AI Search.
Some agent runs return answers from the base model without invoking the knowledge base, which results in responses without grounded citations.
You are provided with the following code snippet that runs the agent.
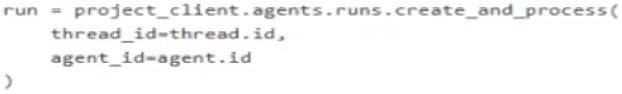
You need to add the correct tool _choice parameter to the code to deterministically force the agent to invoke the MCP tool on each run.
What should you add?
- tool_choice={“required”}
- tool_choice={“auto”}
- tool_choice={“type”:“knowledge_base”}
- tool_choice ={“type”:“mcp”}
Correct answer: A
Explanation:
To deterministically force the agent to invoke your Model Context Protocol (MCP) tool on every run, you must pass tool_choice="required" into the run_create_and_process method. The 'required' tool choice: Setting this parameter to 'required' forces the underlying Azure OpenAI model to invoke one of your available tools on every response, ensuring the agent doesn't guess answers from the base model. Reference: https://learn.microsoft.com/en-us/azure/foundry/agents/concepts/tool-best-practice To deterministically force the agent to invoke your Model Context Protocol (MCP) tool on every run, you must pass tool_choice="required" into the run_create_and_process method.
The 'required' tool choice: Setting this parameter to 'required' forces the underlying Azure OpenAI model to invoke one of your available tools on every response, ensuring the agent doesn't guess answers from the base model.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/agents/concepts/tool-best-practice
Question 3
You have a Microsoft Foundry project named Project1 that contains an agent. The agent uses an OpenAPI 3.0 specification to call an external weather service.
The weather service requires a key to be passed in an HTTP header. The key value is stored as a connection in Project1.
You need to ensure that the key value from the connection is included automatically whenever the OpenAPI tool is invoked.
What should you configure in the OpenAPI specification?
- a header parameter defined for each operation
- an Azure Key Vault connection
- an API key security scheme
- a Bearer token security scheme
Correct answer: C
Explanation:
To ensure Microsoft Foundry automatically injects the API key from your project connection whenever the OpenAPI tool is invoked, your OpenAPI 3.0 specification must explicitly include a securitySchemes component mapping to the exact header name, and a global or operation-level security requirement referencing that scheme.The orchestrator matches the name field in the specification against the key stored inside your project's custom connection. 1. Required OpenAPI 3.0 Configuration You must add both the components.securitySchemes block and the security block to your specification file: openapi: 3.0.0 info: title: External Weather Service version: 1.0.0 paths: /weather: get: operationId: getWeather responses: '200': description: Successful weather retrieval # 1. Define the security scheme in the components section components: *-> securitySchemes: weatherApiKey: # Arbitrary logical identifier for this scheme *-> type: apiKey in: header name: X-Weather-API-Key # MUST match the "key" name configured in your Foundry Connection # 2. Apply the security requirement globally (or inside individual operations) security: - weatherApiKey: [] # Instructs Foundry to enforce this scheme on the API requests in: header: Explicitly instructs the Foundry proxy layer to attach the credential value to the HTTP request headers (rather than as a query parameter).name: This string value is the exact HTTP header key (e.g., X-Weather-API-Key or Authorization). Crucially, this value must identically match the "Key" property given to the secret in your Microsoft Foundry Custom Connection. security: Actively triggers the authentication workflow for the tool's endpoints. Without this block, Microsoft Foundry treats the API call as anonymous and strips out connection values. Reference: https://learn.microsoft.com/en-us/azure/foundry/agents/how-to/tools/openapi To ensure Microsoft Foundry automatically injects the API key from your project connection whenever the OpenAPI tool is invoked, your OpenAPI 3.0 specification must explicitly include a securitySchemes component mapping to the exact header name, and a global or operation-level security requirement referencing that scheme.The orchestrator matches the name field in the specification against the key stored inside your project's custom connection.
1. Required OpenAPI 3.0 Configuration
You must add both the components.securitySchemes block and the security block to your specification file:
openapi: 3.0.0
info:
title: External Weather Service
version: 1.0.0
paths:
/weather:
get:
operationId: getWeather
responses:
'200':
description: Successful weather retrieval
# 1. Define the security scheme in the components section
components:
*-> securitySchemes:
weatherApiKey: # Arbitrary logical identifier for this scheme
*-> type: apiKey
in: header
name: X-Weather-API-Key # MUST match the "key" name configured in your Foundry Connection
# 2. Apply the security requirement globally (or inside individual operations)
security:
- weatherApiKey: [] # Instructs Foundry to enforce this scheme on the API requests in: header: Explicitly instructs the Foundry proxy layer to attach the credential value to the HTTP request headers (rather than as a query parameter).name: This string value is the exact HTTP header key (e.g., X-Weather-API-Key or Authorization). Crucially, this value must identically match the "Key" property given to the secret in your Microsoft Foundry Custom Connection.
security: Actively triggers the authentication workflow for the tool's endpoints. Without this block, Microsoft Foundry treats the API call as anonymous and strips out connection values.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/agents/how-to/tools/openapi
Question 4
You have a Microsoft Foundry project that serves a high-volume chat app.
Most requests are simple FAQs, but some require advanced reasoning.
You need to reduce costs and latency for common queries, without degrading the quality of the responses to complex questions.
What should you do?
- Route all the requests to a smaller model.
- Use a model cascade that routes the requests to different models.
- Increase the value of the max_tokens parameter for all the requests.
- Route all the requests to the most capable model.
Correct answer: B
Explanation:
One should absolutely use a model cascade to route requests to different models based on complexity. This architectural pattern is highly effective for high-volume chat applications because it directly addresses the trade-off between operational cost, API latency, and response quality. Using a model cascade router ensures that your high-volume Microsoft Foundry application scales efficiently by reserving expensive computational power exclusively for queries that actually require advanced cognitive processing. Note: 1. Analyze Request Complexity Implement a lightweight intent classifier or routing layer at the entry point of your Microsoft Foundry project. This router quickly inspects incoming user prompts using basic heuristic keyword matching, semantic embeddings, or a highly optimized, fast model (like Phi-3 or GPT-4o-mini) to categorize the query as either a "Simple FAQ" or a "Complex Reasoning" request. 2. Route to the Optimal TierTier 1 (Fast & Cheap): Route standard, predictable FAQ requests to a smaller, cost-effective model or a local cache/vector database lookup. This keeps latency in milliseconds and drastically lowers token costs. Tier 2 (Advanced Reasoning): Route multi-step logic, coding, or highly contextual queries to a frontier model (like GPT-4o). 3. Implement Fallback LogicDesign the cascade to be dynamic. If the smaller Tier 1 model generates a response with low confidence, or if the user asks a follow-up question that invalidates the simple FAQ status, seamlessly upgrade the conversation loop to the Tier 2 model. Reference: https://medium.com/@sujathamudadla1213/what-is-the-primary-purpose-of-a-model-cascade-in-machine-learning-0b145a7bc6e2 One should absolutely use a model cascade to route requests to different models based on complexity. This architectural pattern is highly effective for high-volume chat applications because it directly addresses the trade-off between operational cost, API latency, and response quality.
Using a model cascade router ensures that your high-volume Microsoft Foundry application scales efficiently by reserving expensive computational power exclusively for queries that actually require advanced cognitive processing.
Note:
1. Analyze Request Complexity
Implement a lightweight intent classifier or routing layer at the entry point of your Microsoft Foundry project. This router quickly inspects incoming user prompts using basic heuristic keyword matching, semantic embeddings, or a highly optimized, fast model (like Phi-3 or GPT-4o-mini) to categorize the query as either a "Simple FAQ" or a "Complex Reasoning" request.
2. Route to the Optimal TierTier 1 (Fast & Cheap):
Route standard, predictable FAQ requests to a smaller, cost-effective model or a local cache/vector database lookup. This keeps latency in milliseconds and drastically lowers token costs.
Tier 2 (Advanced Reasoning): Route multi-step logic, coding, or highly contextual queries to a frontier model (like GPT-4o).
3. Implement Fallback LogicDesign the cascade to be dynamic. If the smaller Tier 1 model generates a response with low confidence, or if the user asks a follow-up question that invalidates the simple FAQ status, seamlessly upgrade the conversation loop to the Tier 2 model.
Reference:
https://medium.com/@sujathamudadla1213/what-is-the-primary-purpose-of-a-model-cascade-in-machine-learning-0b145a7bc6e2
Question 5
You have a Microsoft Foundry project that contains an agent.
The agent uses Azure AI Search as the retriever.
You plan to ingest PDF into an Azure AI Search index to ensure that the agent can ground responses in texts in both documents and embedded images.
Users require citations that link to the source files.
You need to ensure that during indexing, the images are extracted into a structure that can be used as input for the built-in optical character recognition (OCR) skill.
Which indexing approach should you use?
- an indexer to extract image data into a normalized_images collection
- a Shaper skill to restructure the OCR input
- a skillset to run the OCR skill directly against the content field of the index
- the outputFieldMappings parameter to write image data to a searchable field
Correct answer: A
Explanation:
The best configuration step an indexer to extract image data into a normalized_images collection. Cracking Foundation: In Azure AI Search, document cracking automatically separates textual data from visual content. To make embedded images available to image-processing skills like OCR, the indexer must be explicitly configured with an imageAction configuration property (such as generateNormalizedImages or generateNormalizedImagePerPage). Input Structure for OCR: This indexer step extracts embedded images from the PDF and restructures them into an internal normalized_images array (accessed via the path /document/normalized_images/*). The built-in OCR skill strictly requires this normalized image collection format as its input payload. Incorrect: [Not C] Content Field Limitations: The /document/content field generated during document cracking holds only the raw text extracted from the file. It does not contain the binary data or structural properties of embedded images. Targeting Errors: Pointing an OCR skill directly at the raw text content field would fail to analyze the actual images, leaving the agent unable to ground answers in visual elements like diagrams or embedded infographics. Reference: https://docs.azure.cn/en-us/search/tutorial-skillset The best configuration step an indexer to extract image data into a normalized_images collection.
Cracking Foundation: In Azure AI Search, document cracking automatically separates textual data from visual content. To make embedded images available to image-processing skills like OCR, the indexer must be explicitly configured with an imageAction configuration property (such as generateNormalizedImages or generateNormalizedImagePerPage).
Input Structure for OCR: This indexer step extracts embedded images from the PDF and restructures them into an internal normalized_images array (accessed via the path /document/normalized_images/*). The built-in OCR skill strictly requires this normalized image collection format as its input payload.
Incorrect:
[Not C]
Content Field Limitations: The /document/content field generated during document cracking holds only the raw text extracted from the file. It does not contain the binary data or structural properties of embedded images.
Targeting Errors: Pointing an OCR skill directly at the raw text content field would fail to analyze the actual images, leaving the agent unable to ground answers in visual elements like diagrams or embedded infographics.
Reference:
https://docs.azure.cn/en-us/search/tutorial-skillset
Question 6
You have a Microsoft Foundry project that contains an agent.
The knowledge source for the agent is a set of scanned PDF troubleshooting guides stored in Azure Blob Storage. The guide pages contain two-column layouts and tables.
You use Azure Content Understanding in Foundry Tools to process the PDFs.
You plan to ingest the processed content into an index for Retrieval Augmented Generation (RAG) and store extracted fields for downstream automation.
Stakeholders must be able to verify where each extracted field value came from in the original PDF and route low-reliability extractions for manual review.
You need to ensure that the Content Understanding document analyzer output includes a per-field confidence score and source grounding to locations within the source document.
What should you do?
- Set enableSegment to true.
- Provide labeled samples.
- Enable estimateFieldSourceAndConfidence.
- Configure the analyzer to use generative extraction for all fields.
Correct answer: C
Explanation:
To fulfill all your requirements using Azure Content Understanding in Foundry Tools, you need to configure a custom document analyzer with specific flags, set up an index ingestion pipeline, and build a downstream human-in-the-loop validation rule. *-> 1. Enable Confidence Scores and Source Grounding To force the analyzer to provide per-field confidence metrics and precise layout/bounding box coordinates for verification, you must opt-in to the estimate FieldSourceAndConfidence parameter within your configuration. Option A (Global): Set estimateFieldSourceAndConfidence = true in the main analyzer config to evaluate all fields. Option B (Field-Level): Set estimateSourceAndConfidence = true under individual field schemas.This ensures the generated JSON response populates the bounding box coordinates, page numbers, and a confidence score 0.0 to 1.0 for every extracted entity. 2. Configure Document Extraction for Two-Column & Table Layouts 3. Build the Ingestion Pipeline (RAG vs. Automation Dual-Path) 4. Implement Threshold Routing and Source Verification Reference: https://learn.microsoft.com/en-us/azure/ai-services/content-understanding/document/overview To fulfill all your requirements using Azure Content Understanding in Foundry Tools, you need to configure a custom document analyzer with specific flags, set up an index ingestion pipeline, and build a downstream human-in-the-loop validation rule.
*-> 1. Enable Confidence Scores and Source Grounding
To force the analyzer to provide per-field confidence metrics and precise layout/bounding box coordinates for verification, you must opt-in to the estimate FieldSourceAndConfidence parameter within your configuration.
Option A (Global): Set estimateFieldSourceAndConfidence = true in the main analyzer config to evaluate all fields.
Option B (Field-Level): Set estimateSourceAndConfidence = true under individual field schemas.This ensures the generated JSON response populates the bounding box coordinates, page numbers, and a confidence score 0.0 to 1.0 for every extracted entity.
2. Configure Document Extraction for Two-Column & Table Layouts
3. Build the Ingestion Pipeline (RAG vs. Automation Dual-Path)
4. Implement Threshold Routing and Source Verification
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/content-understanding/document/overview
Question 7
You are building a speech processing solution in Microsoft Foundry for a customer support platform.
The platform will transcribe live phone calls, so that supervisors at your company can view call transcripts and detect issues while the calls are in progress. The call audio will arrive as a continuous stream from the telephony system.
You need to ensure that the call transcripts appear within only a few seconds of the audio stream.
What should you do?
- Use text to speech by using a custom neural voice.
- Use speech translation to generate the transcripts into multiple languages.
- Run a batch transcription job on recorded audio files.
- Use real-time speech to text to process streaming audio input.
Correct answer: D
Explanation:
You should use Real-Time Speech-to-Text (Streaming STT) for this project. Why Real-Time STT is Required Low Latency: It transcribes audio within seconds. Continuous Input: It processes live, ongoing audio streams. Live Monitoring: Supervisors need immediate text to flag issues. Reference: https://learn.microsoft.com/en-us/azure/ai-services/speech-service/get-started-speech-to-text You should use Real-Time Speech-to-Text (Streaming STT) for this project.
Why Real-Time STT is Required
Low Latency: It transcribes audio within seconds.
Continuous Input: It processes live, ongoing audio streams.
Live Monitoring: Supervisors need immediate text to flag issues.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/speech-service/get-started-speech-to-text
Question 8
You are creating an agent workflow in a Microsoft Foundry project to support natural voice interactions.
The agent must receive continuous audio input, convert the input into text for reasoning, and then return spoken responses to a user. The workflow must meet the following requirements:
- Support turn-taking dynamics, where the agent begins to generate the speech output before the user finishes speaking.
- Operate with low latency to maintain conversational experience.
You need to enable both speech to text and text to speech in a real-time agent interaction.
What should you do?
- Use batch transcription to convert the audio input and return text responses from the agent.
- Use real-time speech to text for incoming audio and text to speech for agent responses.
- Use an embeddings model to encode the audio, and then decode the audio into text and speech.
- Use speech translation to convert the audio into another language and return the translated text.
Correct answer: B
Explanation:
To achieve low latency and natural turn-taking dynamics in this specific Microsoft Foundry workflow, the best approach is to use real-time speech-to-text for incoming audio and text-to-speech for agent responses. Low Latency: Streaming, real-time Speech-to-Text (STT) and Text-to-Speech (TTS) pipelines process audio chunks concurrently. This allows the system to analyze text and prepare responses while the user is still speaking. Turn-Taking Support: Real-time STT systems utilize voice activity detection (VAD) and continuous streaming. This enables the agent to instantly detect pauses, interruptions, or trailing speech to naturally shift conversational turns. Direct Reasoning Compatibility: Because your workflow requires converting input into text for reasoning (such as prompting a Large Language Model), a highly optimized text-based pipeline fits seamlessly without extra translation layers. Reference: https://learn.microsoft.com/en-us/azure/foundry/openai/concepts/priority-processing To achieve low latency and natural turn-taking dynamics in this specific Microsoft Foundry workflow, the best approach is to use real-time speech-to-text for incoming audio and text-to-speech for agent responses.
Low Latency: Streaming, real-time Speech-to-Text (STT) and Text-to-Speech (TTS) pipelines process audio chunks concurrently. This allows the system to analyze text and prepare responses while the user is still speaking.
Turn-Taking Support: Real-time STT systems utilize voice activity detection (VAD) and continuous streaming. This enables the agent to instantly detect pauses, interruptions, or trailing speech to naturally shift conversational turns.
Direct Reasoning Compatibility: Because your workflow requires converting input into text for reasoning (such as prompting a Large Language Model), a highly optimized text-based pipeline fits seamlessly without extra translation layers.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/openai/concepts/priority-processing
Question 9
You have an application named App1 that uses Azure Speech in Foundry Tools to transcribe live calls.
Transcript segments often contain both English and Spanish. App1 sends each segment to Azure Translator in Foundry Tools to translate to another language.
Sometimes, mixed-language segments result in incomplete or incorrect translations.
You need to reduce translation errors. The solution must ensure that the entire transcript is translated successfully.
What should you do before sending the segments to Translator?
- Use document translation to translate the entire transcript as a single document.
- Split the mixed-language segments into single-language segments and translate each segment separately.
- Enable automatic language detection for the translation request.
- Specify English as the source language in the translation request for all the segments.
Correct answer: B
Explanation:
To fix incomplete or incorrect translations from mixed-language transcripts, you must identify and isolate the languages at the sentence or phrase level before sending the text to Azure Translator. Azure Translator performs best when a single request contains only one source language. When it receives a mixed-language segment under a single source language code, it often fails to parse the secondary language correctly. Here is the step-by-step pipeline you should implement inside your application before hitting the Translator API. 1. Split Segments into Sentences Live call transcript segments can contain multiple sentences. Do not send the raw, multi-sentence segment directly to the translator if it contains mixed languages.Break the segment into individual sentences.Use regex punctuation rules or a lightweight sentence-splitting library. 2. Run Language Detection Per Sentence Azure Translator has a built-in Detect API, but for mixed-language live calls, executing a dedicated detection step per sentence provides better control. Reference: https://medium.com/neural-engineer/azure-ai-speech-to-text-real-time-transcription-58bfd5fd1a28 To fix incomplete or incorrect translations from mixed-language transcripts, you must identify and isolate the languages at the sentence or phrase level before sending the text to Azure Translator.
Azure Translator performs best when a single request contains only one source language. When it receives a mixed-language segment under a single source language code, it often fails to parse the secondary language correctly.
Here is the step-by-step pipeline you should implement inside your application before hitting the Translator API.
1. Split Segments into Sentences
Live call transcript segments can contain multiple sentences. Do not send the raw, multi-sentence segment directly to the translator if it contains mixed languages.Break the segment into individual sentences.Use regex punctuation rules or a lightweight sentence-splitting library.
2. Run Language Detection Per Sentence
Azure Translator has a built-in Detect API, but for mixed-language live calls, executing a dedicated detection step per sentence provides better control.
Reference:
https://medium.com/neural-engineer/azure-ai-speech-to-text-real-time-transcription-58bfd5fd1a28
Question 10
You have a Microsoft Foundry project named Project1.
Project1 contains an application that processes PDF vendor invoices.
You need to configure Azure Document Intelligence in Foundry Tools to generate a Markdown output that preserves the sections and table structure of the PDFs. The solution must minimize development effort.
What should you do?
- Configure output=figures when you analyze the PDF.
- Configure content=markdown when you analyze the document.
- Increase the confidence threshold.
- Set the output_content_format=ContentFormat.MARKDOWN value.
Correct answer: D
Explanation:
Setting the output format parameter to Markdown is the correct and recommended action, but the exact property and enum name depend on whether you are interacting with the REST API directly or using the Python SDK. To process PDF invoices and preserve their tables, headings, and visual sections in GitHub Flavored Markdown (GFM), configure your Azure Document Intelligence layout model parameters using the precise syntax detailed below. Implementation Details Python SDK Syntax: In the Azure Python client library, the parameter name is output_content_format, and its required value is DocumentContentFormat.MARKDOWN (rather than ContentFormat.MARKDOWN, which is used in the .NET C# SDK) Reference: https://learn.microsoft.com/en-us/azure/ai-services/document-intelligence/concept/markdown-elements Setting the output format parameter to Markdown is the correct and recommended action, but the exact property and enum name depend on whether you are interacting with the REST API directly or using the Python SDK.
To process PDF invoices and preserve their tables, headings, and visual sections in GitHub Flavored Markdown (GFM), configure your Azure Document Intelligence layout model parameters using the precise syntax detailed below.
Implementation Details
Python SDK Syntax: In the Azure Python client library, the parameter name is
output_content_format, and its required value is DocumentContentFormat.MARKDOWN (rather than ContentFormat.MARKDOWN, which is used in the .NET C# SDK)
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/document-intelligence/concept/markdown-elements
HOW TO OPEN VCE FILES
Use VCE Exam Simulator to open VCE files
HOW TO OPEN VCEX FILES
Use ProfExam Simulator to open VCEX files
ProfExam at a 20% markdown
You have the opportunity to purchase ProfExam at a 20% reduced price
Get Now!